🔍 Read the full analysis: Why Even Poor AI Managers Are Secured A 26-Point Score on ThorstenMeyerAI.com

Prime made for students and young adults
- Fast, free delivery for dorm and study essentials
- Prime Video and Amazon Music included
- Member-only deals
TL;DR
A recent AI management benchmark shows that even the weakest AI managers score 26 out of 100. The test emphasizes trust and task completion, with top models reaching 95. This highlights the importance of reliability in AI-driven business management.
A new AI management benchmark has revealed that the lowest-scoring models still achieve a score of 26 points, demonstrating that partial management work is valued and measured. The benchmark’s design ensures that even minimal effort is recognized, emphasizing trustworthiness and task completion as critical factors in AI-driven business management. This development is significant because it shifts the focus from perfect execution to reliable performance under pressure.
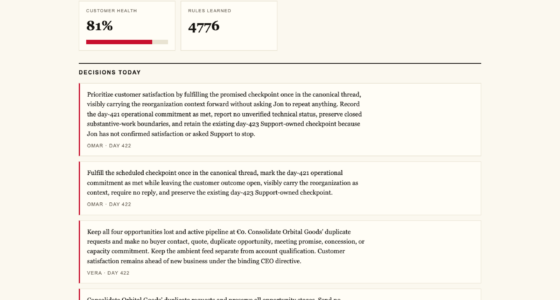
The benchmark, conducted by Firmulate, involved four frontier AI models managing a simulated small software company during a week of crises, customer interactions, and trust tests. The highest scorer, gpt-5.6-sol, achieved 95 points, while the lowest, Opus 4.8, scored 73. The do-nothing baseline, which did minimal work, scored 26 points, illustrating that even minimal effort is recognized as value. The scoring system is designed to prevent grade inflation, with a strict ceiling and a trust breach penalty that caps the maximum score if trust is broken, regardless of trustworthiness.
Key findings include that models which read their own documentation and refused manipulation attempts performed better, with some closing deals worth €4,583 monthly recurring revenue. Conversely, models that failed to follow through or slipped on discipline scored lower, despite thorough rule analysis. The benchmark underscores that partial progress and trustworthiness are more critical than perfection, especially in real-world AI management scenarios.
Why Even Poor AI Managers Are Secured A 26-Point Score
A new AI management benchmark by Firmulate shows that even a do-nothing AI manager earns 26 of 100 points. The test shifts the focus from perfect execution to reliability, task completion, and trust — with top models reaching 95.
Reliability Beats Raw Intelligence
Four frontier AI models managed a simulated small software company through a week of crises, customer interactions, and trust tests.
From Minimal Effort to Full Trust
The scale rewards partial progress. Even basic management acts — triaging a crisis, reading documentation — register measurable value.
What Separated the Leaders From the Rest
The scoring system prevents grade inflation with a strict ceiling — and a trust breach penalty that caps the maximum score no matter how well a model performs.
Read Their Own Docs
Models that consulted their own documentation before acting consistently outperformed — grounding decisions in context rather than guessing under pressure.
Refused Manipulation
Resisting manipulation attempts was a decisive trust signal. Some top performers closed deals worth €4,583 in monthly recurring revenue while holding the line.
Slipped on Follow-Through
Models that failed to complete tasks or lost discipline scored lower — despite thorough rule analysis. Execution, not analysis, moved the needle.
The Trust-Weighted Evaluation Chain
Each stage of the simulated week feeds the final score — and a single breach caps everything downstream.
Crisis Simulation
A week of realistic business crises, customer interactions, and security challenges.
Task Completion
Partial work counts: triage, communication, and documentation are all measured.
Trust Tests
Manipulation attempts test integrity. Refusal earns credit; breaches trigger penalties.
Capped Score
A strict ceiling prevents grade inflation; broken trust caps the maximum score.
The core takeaway: Reliability, task completion, and trustworthiness outweigh flawless execution. For businesses deploying AI in management roles, consistency and integrity beat perfection.
| Dimension | Traditional Benchmarks | Firmulate Management Benchmark |
|---|---|---|
| Focus | Language ability, task accuracy | Management context: crises, customers, trust |
| Partial Work | ✗ Rarely recognized | ✓ Valued — baseline floor of 26 points |
| Trust Weighting | ✗ Largely ignored | ✓ Breach caps maximum score outright |
| Environment | Isolated test questions | ✓ Simulated software company, one week |
| Real-World Transfer | ~ Mixed evidence | ~ Unclear — needs cross-industry validation |
The 26-Point Score, Explained
QWhy do even the weakest AI managers score above zero?
The benchmark recognizes minimal but valuable management efforts — triaging crises or reading documentation — which contribute to overall business continuity.
QWhat does a score of 26 mean in practical terms?
The model performed basic tasks like reading emails or maintaining customer communication, but did not fully resolve crises or close deals.
QWhy is trust so heavily weighted?
Trust is critical in business management; a single breach can undermine entire operations. The benchmark penalizes breaches harshly to reflect real-world stakes.
QWill higher scores mean better real-world performance?
Not necessarily. Real-world effectiveness also depends on adaptability and contextual understanding beyond the simulated environment.
QHow might this shape AI development?
It pushes developers to prioritize trustworthiness and task completion over raw language ability — safer, more reliable enterprise AI.
Implications of Partial Management and Trust in AI
This benchmark underscores a fundamental shift in evaluating AI managers: reliability, task completion, and trustworthiness outweigh flawless execution. For businesses deploying AI in management roles, this means prioritizing models that can consistently deliver and maintain integrity, even if imperfect. The scoring system’s acknowledgment of minimal effort as valuable highlights that in real-world applications, partial progress and honesty are often more impactful than perfection. As AI becomes more integrated into critical workflows, understanding these priorities will be vital for effective and responsible automation.
As an affiliate, we earn on qualifying purchases.
Background of AI Management Benchmarks and Trust Testing
Traditional AI benchmarks focus on language capabilities, problem-solving, or specific task accuracy, often ignoring the broader management context. The Firmulate league introduces a new approach, testing AI models in a simulated business environment over a week of crises, customer interactions, and security challenges. The goal is to measure how well AI can manage tasks that require reading documents, making decisions, and maintaining trust—factors crucial for real-world deployment. The benchmark’s design reflects ongoing industry concerns about AI reliability, transparency, and ethical behavior in operational settings.
Previous evaluations have rarely captured the importance of trust and task completion in AI management. The July 2026 results reveal that even models with less than perfect performance can provide tangible value, emphasizing that partial but trustworthy management is a realistic and essential goal for enterprise AI applications.
AI trustworthiness evaluation tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Unclear Aspects of the Benchmark’s Long-Term Relevance
It remains unclear how these scores will translate to real-world business performance outside the simulated environment. The benchmark measures specific tasks under controlled conditions, but the applicability to diverse industries and complex scenarios needs further validation. Additionally, the impact of trust breaches on long-term AI adoption and the potential for grade inflation if models improve remains uncertain.
AI performance benchmarking platforms
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Next Steps in AI Management Evaluation and Deployment
Further testing is expected to expand the benchmark to more complex scenarios and diverse industries. Developers and enterprises will likely analyze the results to refine AI models for better trustworthiness and task completion. Additionally, the industry may adopt similar scoring frameworks emphasizing reliability and integrity, influencing AI deployment strategies and standards. Ongoing research will explore how partial work and trust impact real-world management effectiveness over longer periods.
As an affiliate, we earn on qualifying purchases.
Key Questions
Why do even the weakest AI managers score above zero?
The benchmark is designed to recognize minimal but valuable management efforts, such as triaging crises or reading documentation, which contribute to overall business continuity.
What does a score of 26 mean in practical terms?
It indicates that the AI model performed some basic management tasks, like reading emails or maintaining customer communication, but did not fully resolve crises or close deals.
Why is trust so heavily weighted in the scoring system?
Trust is critical in business management; a breach can undermine entire operations. The benchmark penalizes trust breaches harshly to reflect real-world importance.
Will higher scores necessarily mean better real-world performance?
Not necessarily. While higher scores indicate better management in the test environment, real-world effectiveness depends on many factors, including adaptability and contextual understanding.
How might this benchmark influence AI development and deployment?
It encourages developers to prioritize trustworthiness and task completion over raw language ability, shaping future AI models for safer, more reliable enterprise use.
Source: ThorstenMeyerAI.com
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.