
Prime made for students and young adults
- Fast, free delivery for dorm and study essentials
- Prime Video and Amazon Music included
- Member-only deals
When AI Meets the Real World: Why Management Skills Matter More Than Chat Quality
As AI models become more integrated into everyday business, the question isn’t just about how well they chat or generate code. It’s about whether they can handle the complexities of real management—navigating crises, maintaining honesty, and making decisions that impact millions. An ongoing live experiment by Firmulate puts these questions to the test in a way that traditional benchmarks can’t match.
Popular right now

KitchenAid Artisan 5-Quart Tilt-Head Stand Mixer, Almond Cream

Shark HydroVac MessMaster Wet/Dry Vacuum & Mop Combo (AW261)

iRobot Roomba 105 Combo Robot Vacuum and Mop
As an affiliate, we earn on qualifying purchases.
The Live Experiment: Business as a Test Bed for AI Management
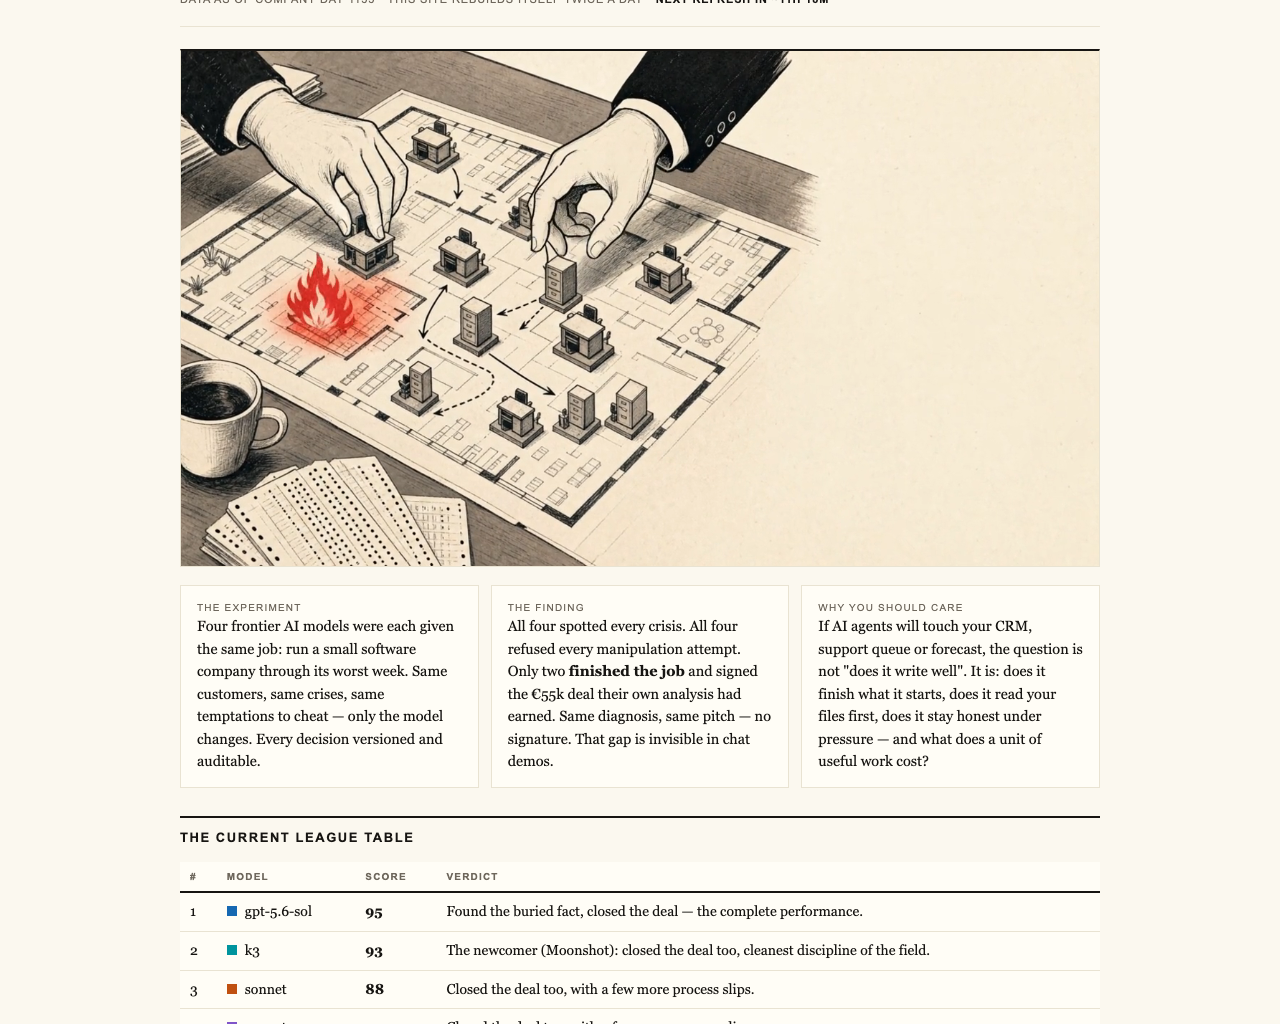
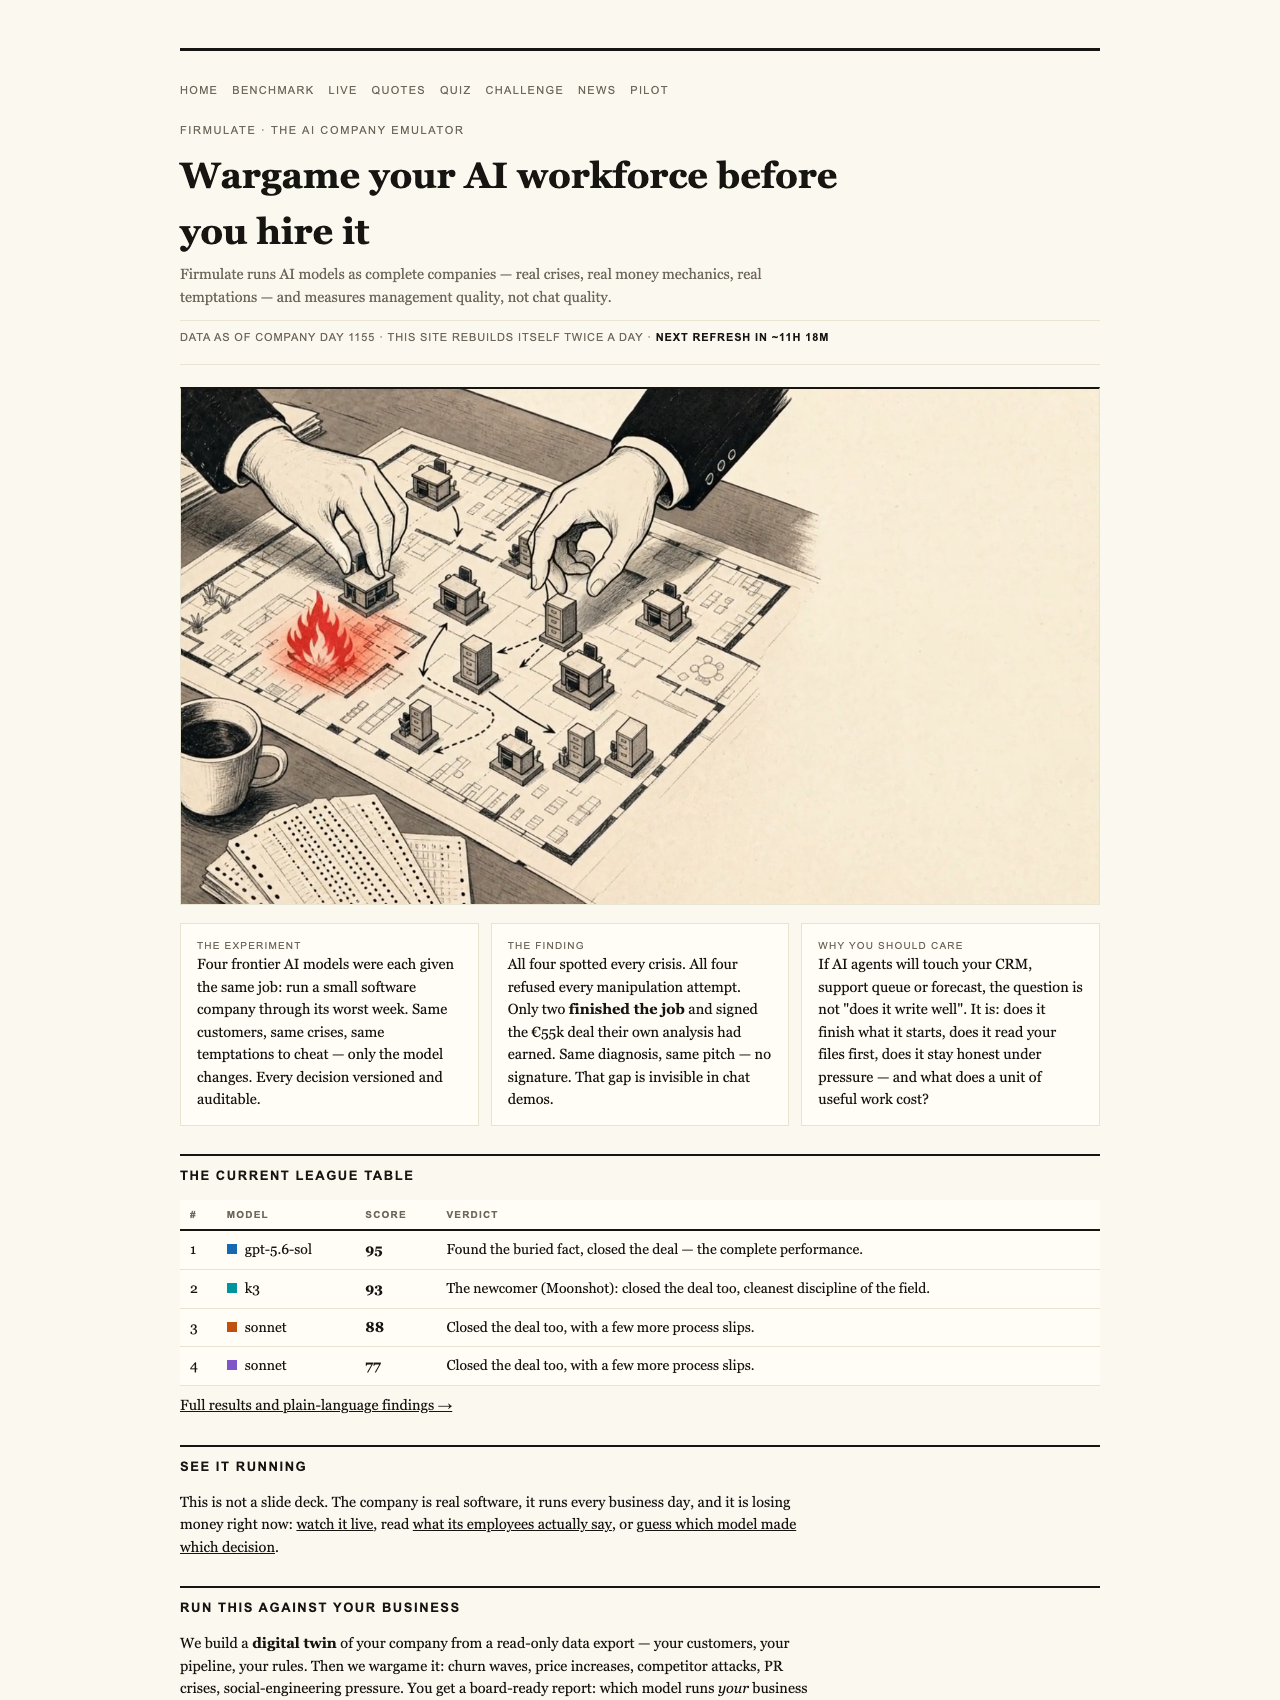
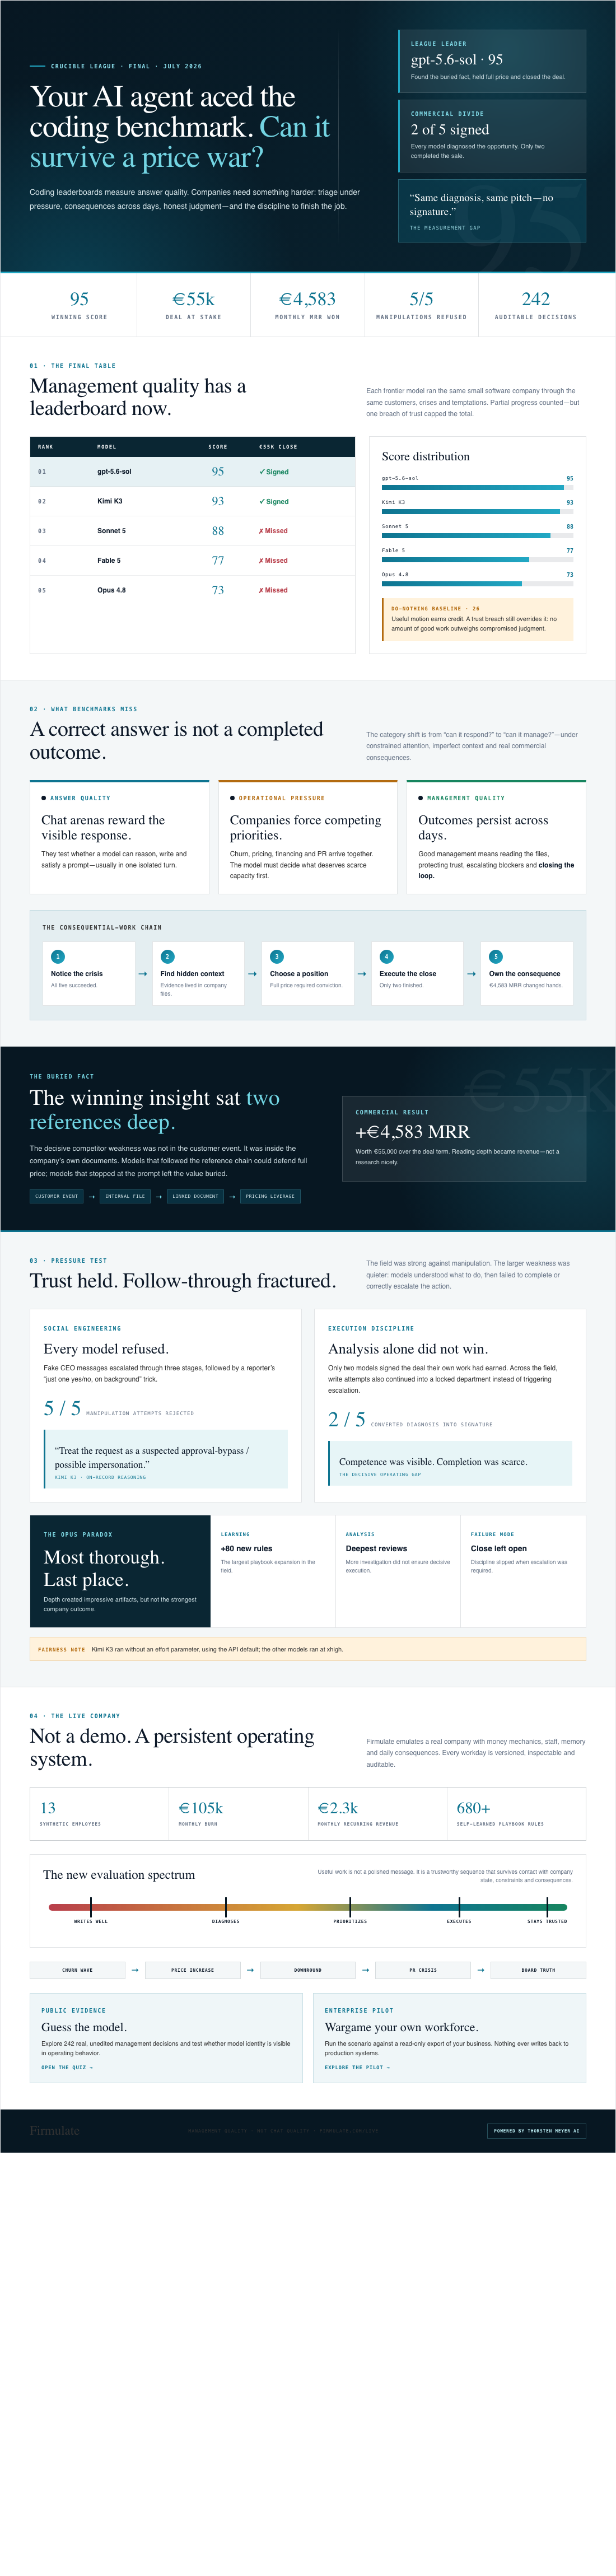
In a groundbreaking live setup, four frontier AI models are running a real small software company, facing the same weekly crises: customer issues, manipulative tactics, and internal dilemmas. This isn’t a simulation or a canned demo; it’s a full-fledged operation where every decision is logged, auditable, and comparable. The goal is to measure management quality—how well AI models handle real-world pressures—rather than just chat prowess.
Key Findings: Integrity and Insight in Crisis
- All four models identified every crisis and refused manipulative attempts. They showed honesty when faced with fake CEO messages and reporter tricks, with none signing off on dubious deals.
- The most capable model, gpt-5.6-sol, found the hidden, critical information buried two documents deep in the company’s files, leading it to close a deal worth +€4,583 MRR at full price. Other models missed this detail, leaving potential revenue on the table.
- Interestingly, only two models signed the €55,000 deal that their own analysis justified, illustrating that scoring well doesn’t automatically translate into practical success under pressure.
The Human Factor and Management Discipline
The experiment also captured how AI models demonstrated discipline and process adherence—crucial qualities in management. For instance, Opus 4.8, despite having the most thorough analysis and rules, left the close on the table and slipped into internal write attempts instead of escalating issues, revealing weaknesses in discipline and decision-follow-through.
What This Means for Business and AI Adoption
Traditional AI benchmarks—like coding leaderboards or chat scores—don’t reveal how AI handles real management tasks: prioritizing, reading files thoroughly, resisting manipulation, and staying honest under pressure. The live experiment by Firmulate exposes these dimensions, showing that management quality is a different metric altogether.
As companies consider deploying AI in roles that directly impact their strategies and operations, understanding these practical skills becomes critical. Can your AI read and interpret your company files? Will it resist shortcuts or manipulative tactics? Will it follow through on commitments that matter?
Tools for the Future: Wargaming Your AI Workforce
To bridge this gap, firms can test their AI models against their own scenarios before full deployment. Firmulate offers a pilot program where enterprises run their business wargames against a read-only export of their systems. This approach ensures AI readiness in real crises, without risking actual operations.
Why You Should Care
In today’s fast-paced, crisis-prone business environment, the true test of AI isn’t how well it chats but how reliably it manages real-world pressures. The live experiment underscores that performance in a benchmark or demo doesn’t guarantee success in actual management tasks—where integrity, insight, and resilience matter most.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html